Online or onsite, instructor-led live Big Data training courses start with an introduction to elemental concepts of Big Data, then progress into the programming languages and methodologies used to perform Data Analysis. Tools and infrastructure for enabling Big Data storage, Distributed Processing, and Scalability are discussed, compared and implemented in demo practice sessions.
Big Data training is available as "online live training" or "onsite live training". Online live training (aka "remote live training") is carried out by way of an interactive, remote desktop. Cardiff onsite live Big Data trainings can be carried out locally on customer premises or in NobleProg corporate training centers.
NobleProg -- Your Local Training Provider
Cardiff
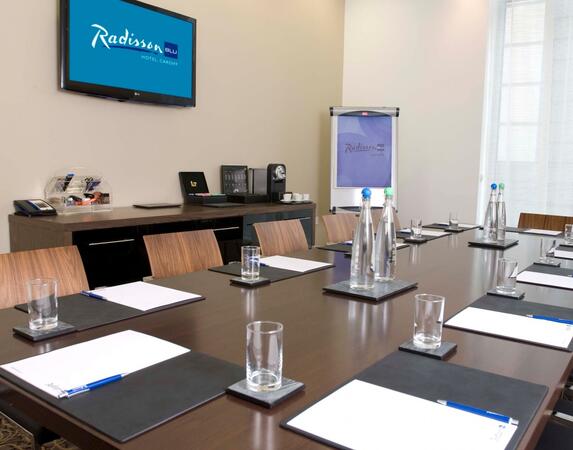
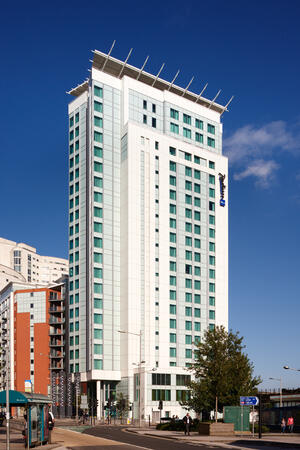
Radisson Blu Hotel, Meridian Gate - Bute Terrace, Cardiff, united kingdom, CF10 2FL
The Radisson Blu Hotel in Cardiff city centre is the perfect hub for your Welsh adventure
Close to several public transportation options, our hotel in Cardiff puts the city centre at your fingertips. Catch a train or a bus at one of the nearby stations, or take the M4 motorway and drive wherever you want to go in Wales and beyond. For those flying into the city, the Cardiff International Airport is just a 30-minute drive from the hotel. You’ll find parking around the hotel at the John Lewis, St David’s II and NCP Pellet Street car parks, plus some parking at the hotel. Enjoy shopping and dining within walking distance of the hotel, and explore the colourful history of this thriving capital city.
The hotel is located on Bute Terrace providing easy access to the M4 at junction 32 only 6 km away.
The central train and bus station is located within a five-minute walk from the hotel.
Cardiff International Airport is located 24 km from the hotel and can be reached by bus, train or taxi.
This instructor-led, live training in Cardiff (online or onsite) is aimed at intermediate-level data scientists and engineers who wish to use Google Colab and Apache Spark for big data processing and analytics.
By the end of this training, participants will be able to:
Set up a big data environment using Google Colab and Spark.
Process and analyze large datasets efficiently with Apache Spark.
Visualize big data in a collaborative environment.
This instructor-led live training in Cardiff covers the Stratio platform, focusing on the Rocket and Intelligence modules with PySpark. Participants will master data ingestion, transformation, and advanced analytics, gaining practical skills in loops, UDFs, and enterprise data workflows.
This live training in Cardiff covers data warehousing concepts, dimensional modeling, and ETL pipeline design. Participants will build star schemas, optimise OLAP workloads, and implement governance, gaining practical skills for building robust analytical systems.
Participants who complete this instructor-led, live training in Cardiff will gain a practical, real-world understanding of Big Data and its related technologies, methodologies and tools.
Participants will have the opportunity to put this knowledge into practice through hands-on exercises. Group interaction and instructor feedback make up an important component of the class.
The course starts with an introduction to elemental concepts of Big Data, then progresses into the programming languages and methodologies used to perform Data Analysis. Finally, we discuss the tools and infrastructure that enable Big Data storage, Distributed Processing, and Scalability.
This live training in Cardiff helps intermediate to advanced users master Greenplum architecture and data modeling. Participants will learn to design distributed tables, apply high-performance SQL, and interpret EXPLAIN plans for optimal query execution in large-scale analytic environments.
This instructor-led training in Cardiff covers Greenplum installation, updates, and library management. Participants learn to configure clusters, apply safe patches, and handle extensions for advanced analytics, building practical skills for real-world environments.
This instructor-led, live training in Cardiff (online or onsite) is aimed at advanced-level data professionals who wish to optimise data processing workflows, ensure data integrity, and implement robust data lakehouse solutions that can handle the complexities of modern big data applications.
By the end of this training, participants will be able to:
Gain an in-depth understanding of Iceberg’s architecture, including metadata management and file layout.
Configure Iceberg for optimal performance in various environments and integrate it with multiple data processing engines.
This instructor-led, live training in Cardiff (online or onsite) is aimed at beginner-level data professionals who wish to acquire the knowledge and skills necessary to effectively utilize Apache Iceberg for managing large-scale datasets, ensuring data integrity, and optimizing data processing workflows.
By the end of this training, participants will be able to:
Gain a thorough understanding of Apache Iceberg's architecture, features, and benefits.
Learn about table formats, partitioning, schema evolution, and time travel capabilities.
Install and configure Apache Iceberg in different environments.
Create, manage, and manipulate of Iceberg tables.
Understand the process of migrating data from other table formats to Iceberg.
This instructor-led, live training in Cardiff (online or onsite) is aimed at intermediate-level IT professionals who wish to enhance their skills in data architecture, governance, cloud computing, and big data technologies to effectively manage and analyze large datasets for data migration within their organizations.
By the end of this training, participants will be able to:
Understand the foundational concepts and components of various data architectures.
Gain a comprehensive understanding of data governance principles and their importance in regulatory environments.
Implement and manage data governance frameworks such as Dama and Togaf.
Leverage cloud platforms for efficient data storage, processing, and management.
This instructor-led, live training in Cardiff (online or onsite) is aimed at intermediate-level data engineers who wish to learn how to use Azure Data Lake Storage Gen2 for effective data analytics solutions.
By the end of this training, participants will be able to:
Understand the architecture and key features of Azure Data Lake Storage Gen2.
Optimize data storage and access for cost and performance.
Integrate Azure Data Lake Storage Gen2 with other Azure services for analytics and data processing.
Develop solutions using the Azure Data Lake Storage Gen2 API.
Troubleshoot common issues and optimise storage strategies.
This instructor-led, live training in Cardiff (online or onsite) is aimed at developers who wish to use and integrate Spark, Hadoop, and Python to process, analyze, and transform large and complex data sets.
By the end of this training, participants will be able to:
Set up the necessary environment to start processing big data with Spark, Hadoop, and Python.
Understand the features, core components, and architecture of Spark and Hadoop.
Learn how to integrate Spark, Hadoop, and Python for big data processing.
Explore the tools in the Spark ecosystem (Spark MlLib, Spark Streaming, Kafka, Sqoop, Kafka, and Flume).
Build collaborative filtering recommendation systems similar to Netflix, YouTube, Amazon, Spotify, and Google.
Use Apache Mahout to scale machine learning algorithms.
This instructor-led live training in Cardiff covers advanced big data techniques, distributed computing, and machine learning at scale. It is designed for advanced data professionals aiming to master real-time analytics, deep learning integration, and robust data governance strategies.
This instructor-led, live training in Cardiff (online or onsite) is aimed at intermediate-level IT professionals who wish to have a comprehensive understanding of IBM DataStage from both an administrative and a development perspective, allowing them to manage and utilize this tool effectively in their respective workplaces.
By the end of this training, participants will be able to:
Understand the core concepts of DataStage.
Learn how to effectively install, configure, and manage DataStage environments.
Connect to various data sources and extract data efficiently from databases, flat files, and external sources.
This instructor-led, live training in Cardiff (online or onsite) is aimed at beginner-level to intermediate-level system administrators who wish to deploy, maintain, and optimise Spark clusters.
By the end of this training, participants will be able to:
Install and configure Apache Spark in various environments.
Manage cluster resources and monitor Spark applications.
Optimize the performance of Spark clusters.
Implement security measures and ensure high availability.
In this instructor-led, live training in Cardiff, participants will learn how to use Python and Spark together to analyze big data as they work on hands-on exercises.
By the end of this training, participants will be able to:
Learn how to use Spark with Python to analyze Big Data.
Work on exercises that mimic real world cases.
Use different tools and techniques for big data analysis using PySpark.
This live training in Cardiff helps developers and analysts master SQL for big data. Participants learn to query large datasets efficiently using MySQL, Postgres, HiveQL, and Redshift, while exploring data modeling and NoSQL systems to wrangle data into reporting tools effectively.
Explore Big Data BI for government agencies in Cardiff. This course covers Hadoop, NoSQL, predictive analytics, and real-time tools to manage vast, diverse data streams. Learn fraud detection, cybersecurity, and ROI strategies to transform unstructured data into strategic assets for mission success.
In this instructor-led, live training in Cardiff, participants will learn the mindset with which to approach Big Data technologies, assess their impact on existing processes and policies, and implement these technologies for the purpose of identifying criminal activity and preventing crime. Case studies from law enforcement organizations around the world will be examined to gain insights on their adoption approaches, challenges and results.
By the end of this training, participants will be able to:
Combine Big Data technology with traditional data gathering processes to piece together a story during an investigation.
Implement industrial big data storage and processing solutions for data analysis.
Prepare a proposal for the adoption of the most adequate tools and processes for enabling a data-driven approach to criminal investigation.
Explore the fundamentals of programming with Big Data in R, a language popular in finance. This course in Cardiff covers environment setup, MPI for parallel processing, and distributed matrices. Learn to handle large datasets, perform distributed regression, and apply Monte Carlo methods efficiently.
This instructor-led, live training (online or onsite) is aimed at data engineers, data analysts, and data professionals who wish to use Databricks and PySpark to build scalable data pipelines and migrate existing SQL workflows.
In Cardiff, this five-day training introduces real time data streaming systems. It covers core concepts, architecture patterns, and industry tools for processing continuous data at scale. Learners design, implement, and optimise scalable streaming pipelines using modern frameworks.
This instructor-led live training in Cardiff is designed for intermediate administrators aiming to deploy and manage Apache NiFi in production. Participants will learn to configure clusters, design dataflows, and optimise performance through hands-on labs and scenario-based exercises.
This training provides a practical introduction to building scalable data processing and Machine Learning workflows using PySpark. Participants learn how Apache Spark operates within modern Big Data ecosystems and how to efficiently process large datasets using distributed computing principles.
This three-day practical course focuses on building and optimising efficient data-processing workloads using PySpark, Pandas and Polars in Kubernetes-based environments.
Participants will develop a practical understanding of how Spark applications execute on Kubernetes and how application-level configuration decisions influence performance, scalability, resource consumption and cost. The course covers key optimisation areas including executor sizing, memory allocation, dynamic allocation, partitioning strategies, shuffle behaviour, small-file problems and efficient Parquet processing.
The course also addresses common challenges when working with Pandas, including memory limitations and out-of-memory failures, and introduces Polars as a high-performance alternative for selected data-processing workloads. Through hands-on exercises, participants will diagnose performance and memory issues, compare different configuration strategies and apply optimisation techniques to realistic ETL and machine learning scenarios.
The emphasis throughout the course is on practical decision-making: understanding how to identify bottlenecks, select the appropriate tool, configure Spark efficiently and balance performance with infrastructure resource consumption and cost.
This instructor-led, live training in Cardiff (online or onsite) is aimed at engineers who wish to set up and deploy Apache Spark system for processing very large amounts of data.
By the end of this training, participants will be able to:
Install and configure Apache Spark.
Quickly process and analyze very large data sets.
Understand the difference between Apache Spark and Hadoop MapReduce and when to use which.
Integrate Apache Spark with other machine learning tools.
This hands-on training in Cardiff demystifies Apache Spark, covering RDDs, DataFrames, and Python/Scala APIs. Participants will master cloud deployment with Databricks, AWS EMR, and Glue, building practical skills for real-world data engineering and DevOps tasks effectively.
This instructor-led, live training in Cardiff (online or onsite) is aimed at technical persons who wish to deploy Talend Open Studio for Big Data to simplifying the process of reading and crunching through Big Data.
By the end of this training, participants will be able to:
Install and configure Talend Open Studio for Big Data.
Connect with Big Data systems such as Cloudera, HortonWorks, MapR, Amazon EMR and Apache.
Understand and set up Open Studio's big data components and connectors.
Configure parameters to automatically generate MapReduce code.
Use Open Studio's drag-and-drop interface to run Hadoop jobs.
Prototype big data pipelines.
Automate big data integration projects.
Read more...
Last Updated:
Testimonials (8)
A journey through the Spark world: a very intense course. DSL, spark sql, partitioning vs bucketing for me.
Georgiana Elisabeta
Course - Apache Spark Fundamentals
the practices
Liliana Padilla - Hipodromo de Agua Caliente
Course - Greenplum Architecture and Data Modeling
Gunnar adjusted the content for the second day based on our feedback from day one. He checked in with us to find out what we liked, disliked, found hard and how we wanted to approach day 2.
I liked Gunnar's style of teaching: Lecture, share examples, allowed us time to practice and answer questions before moving to the next subject. It meant we could fully understand a topic before moving onto the next subject. This reduced overload of information and gave us a chance to spend more time on the topics we struggled with and less time on the stuff we found easy.
Ffion - Complete Coherence
Course - SQL For Data Science and Data Analysis
Hands on exercises. Class should have been 5 days, but the 3 days helped to clear up a lot of questions that I had from working with NiFi already
James - BHG Financial
Course - Apache NiFi for Administrators
The ability of the trainer to align the course with the requirements of the organization other than just providing the course for the sake of delivering it.
Masilonyane - Revenue Services Lesotho
Course - Big Data Business Intelligence for Govt. Agencies
The fact that we were able to take with us most of the information/course/presentation/exercises done, so that we can look over them and perhaps redo what we didint understand first time or improve what we already did.
Raul Mihail Rat - Accenture Industrial SS
Course - Python, Spark, and Hadoop for Big Data
Having hands on session / assignments
Poornima Chenthamarakshan - Intelligent Medical Objects
Course - Apache Spark in the Cloud
The subject matter and the pace were perfect.
Tim - Ottawa Research and Development Center, Science Technology Branch, Agriculture and Agri-Food Canada
Course - Programming with Big Data in R
Provisional Upcoming Courses (Contact Us For More Information)
Online Big Data training in Cardiff, Big Data training courses in Cardiff, Weekend Big Data courses in Cardiff, Evening Big Data training in Cardiff, Big Data instructor-led in Cardiff, Big Data private courses in Cardiff, Big Data classes in Cardiff, Online Big Data training in Cardiff, Weekend Big Data training in Cardiff, Big Data coaching in Cardiff, Evening Big Data courses in Cardiff, Big Data trainer in Cardiff, Big Data one on one training in Cardiff, Big Data boot camp in Cardiff, Big Data instructor-led in Cardiff, Big Data on-site in Cardiff, Big Data instructor in Cardiff