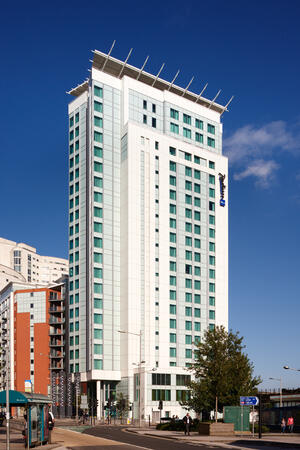
Radisson Blu Hotel, Meridian Gate - Bute Terrace, Cardiff, united kingdom, CF10 2FL
The Radisson Blu Hotel in Cardiff city centre is the perfect hub for your Welsh adventure
Close to several public transportation options, our hotel in Cardiff puts the city centre at your fingertips. Catch a train or a bus at one of the nearby stations, or take the M4 motorway and drive wherever you want to go in Wales and beyond. For those flying into the city, the Cardiff International Airport is just a 30-minute drive from the hotel. You’ll find parking around the hotel at the John Lewis, St David’s II and NCP Pellet Street car parks, plus some parking at the hotel. Enjoy shopping and dining within walking distance of the hotel, and explore the colourful history of this thriving capital city.
- The hotel is located on Bute Terrace providing easy access to the M4 at junction 32 only 6 km away.
- The central train and bus station is located within a five-minute walk from the hotel.
- Cardiff International Airport is located 24 km from the hotel and can be reached by bus, train or taxi.