Delivered either online or on-site, our instructor-led live PySpark training courses provide hands-on practical experience in utilising Python and Spark in tandem to analyse large-scale datasets.
PySpark training is offered as either 'online live training' or 'on-site live training'. Online live sessions (also known as 'remote live training') are conducted through an interactive, remote desktop environment. On-site live training can be hosted directly at your client's premises in Glasgow or at NobleProg's corporate training centres located in Glasgow.
NobleProg -- Your Local Training Provider
Glasgow
69 Buchanan St, Glasgow, united kingdom, G1 3HL
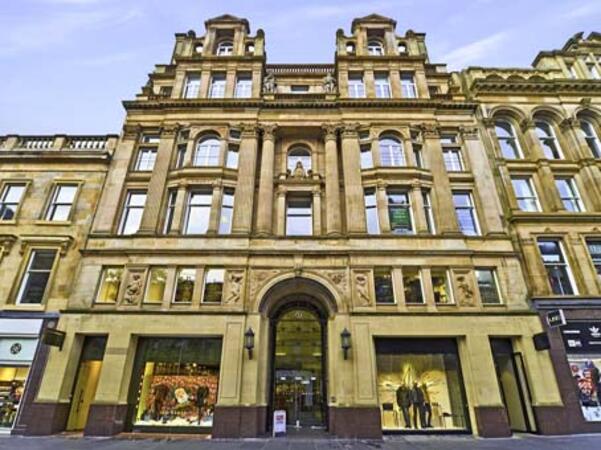
The Buchanan Street Centre is located in the heart of Glasgow, in Scotland's most famous shopping and retail district. A major feature of this stunning large Victorian building is the impressive sandstone entrance archway giving access to four floors. Glasgow's fantastic array of shops, hotels, restaurants and bars are on the doorstep and Buchanan Street itself is home to a number of exclusive shops and recently won the Academy of Urbanism 'Great Street Award'. One of the fastest growing cities in the UK, Glasgow is Scotland's largest urban economy and is dominated by financial and business services, public administration, health and retail. It is one of Europe's 16 largest financial centres with a growing number of 'blue-chip' financial sector companies establishing significant operations or headquarters in the city. It also forms the western part of Scotland's 'Silicon Glen' hi-tech sector.
This instructor-led live training in Glasgow covers the Stratio platform, focusing on the Rocket and Intelligence modules with PySpark. Participants will master data ingestion, transformation, and advanced analytics, gaining practical skills in loops, UDFs, and enterprise data workflows.
In this instructor-led, live training in Glasgow, participants will learn how to utilise Python and Spark in tandem to analyse big data, supported by hands-on exercises.
By the end of this training, participants will be able to:
Learn how to use Spark with Python to analyse Big Data.
Work on exercises that mirror real-world scenarios.
Use different tools and techniques for big data analysis using PySpark.
This live, instructor-led training (available online or on-site) is tailored for data engineers, analysts, and professionals aiming to utilise Databricks and PySpark to build scalable data pipelines and migrate established SQL workflows.
This training provides a practical introduction to constructing scalable data processing and Machine Learning workflows using PySpark. It covers the operation of Apache Spark within modern Big Data ecosystems and the efficient processing of large datasets through distributed computing principles.
This three-day practical course focuses on building and optimising efficient data-processing workloads using PySpark, Pandas and Polars in Kubernetes-based environments.
Participants will develop a practical understanding of how Spark applications execute on Kubernetes and how application-level configuration decisions influence performance, scalability, resource consumption and cost. The course covers key optimisation areas including executor sizing, memory allocation, dynamic allocation, partitioning strategies, shuffle behaviour, small-file problems and efficient Parquet processing.
The course also addresses common challenges when working with Pandas, including memory limitations and out-of-memory failures, and introduces Polars as a high-performance alternative for selected data-processing workloads. Through hands-on exercises, participants will diagnose performance and memory issues, compare different configuration strategies and apply optimisation techniques to realistic ETL and machine learning scenarios.
The emphasis throughout the course is on practical decision-making: understanding how to identify bottlenecks, select the appropriate tool, configure Spark efficiently and balance performance with infrastructure resource consumption and cost.
Read more...
Last Updated:
Testimonials (2)
Showing different ways to optimise our PySpark queries.
Ivan Abrashev - UBB + DZI (KBC GROUP)
Course - Efficient Data Processing on Kubernetes with PySpark, Pandas & Polars
I liked that it was practical. Loved to apply the theoretical knowledge with practical examples.
Aurelia-Adriana - Allianz Services Romania
Course - Python and Spark for Big Data (PySpark)
Provisional Upcoming Courses (Contact Us For More Information)
Online PySpark training in Glasgow, PySpark training courses in Glasgow, Weekend PySpark courses in Glasgow, Evening PySpark training in Glasgow, PySpark instructor-led in Glasgow, PySpark coaching in Glasgow, PySpark instructor in Glasgow, PySpark instructor-led in Glasgow, PySpark private courses in Glasgow, Evening PySpark courses in Glasgow, PySpark one on one training in Glasgow, PySpark on-site in Glasgow, PySpark boot camp in Glasgow, PySpark classes in Glasgow, Weekend PySpark training in Glasgow, Online PySpark training in Glasgow, PySpark trainer in Glasgow